Technology
Purpose-built chips for fast AI inference
We run open models on hardware chosen for the job. For fast inference, that is SambaNova's SN40L today: chips that stream the model through the chip instead of shuttling data back and forth to memory, so answers arrive sooner.
Output Throughput, p50, 10K input / 1K output, single request. Last measured: July 2026.
Inference is a memory problem, not a compute problem
A language model writes its answer one token at a time. For every token, a GPU fetches the model's weights from memory, computes, and writes the result back. The trip to memory takes far longer than the computation, so in this phase, called decode, the GPU spends most of its time waiting. Providers hide the wait by batching many users together: the system produces more tokens in total, but each answer arrives more slowly.
Dataflow: no detours through memory
SambaNova's chip, the RDU (Reconfigurable Dataflow Unit), lays out the operations of a whole model layer across the chip and streams data through them. The weights come from the high-bandwidth memory (HBM) in the same package. Everything computed in between stays on the chip, instead of going back to memory after every step. That lets the chip use close to 85% of its memory bandwidth for the weights (SambaNova, SN40L paper).
Each chip can address the memory of all 16 chips in a rack. One rack therefore serves models with several hundred billion parameters.
The trade-off
A chip serves a small batch of requests at a time. That keeps each answer fast. For bulk jobs where nobody waits for the answer, maximum batch throughput matters more than speed per request.
What this changes in practice
Developers
Fast tokens for every request, not only in aggregate: 713 tok/s on gpt-oss-120b and 428 tok/s on MiniMax M2.7, measured on our API. An agent finishes more steps in the same time.
Platform teams
Large models on one rack. Several models stay in memory at once and switch in milliseconds, so a dedicated rack can serve your fine-tuned checkpoints side by side. Long contexts: 192K tokens on MiniMax M2.7, 128K on gpt-oss-120b and Gemma 4. On MiniMax M2.7, repeated context is served from a prompt cache in the chips' memory and never written to disk.
Leadership and sustainability
Less data movement is what makes the chip fast, and it also saves energy: a request that finishes sooner draws power for a shorter time, and a large model fits on fewer chips. SambaNova reports up to 5x better energy efficiency than a GPU (2.5x-5.6x against an NVIDIA H200 with Llama 70B, depending on batch size, 2025). A rack draws about 10 kW in typical use and is air-cooled, so it fits the data centers that exist today.
How we choose what runs underneath
We are an inference provider, not a chip maker. We judge any hardware by five questions, in this order:
- 01
Does it fit the data centers Europe has?
Power and cooling come first. Air-cooled racks go anywhere; capacity for liquid cooling is scarce.
- 02
Is there a complete software stack?
A chip is not a service. We need the compiler, runtime and serving layer that turn it into an API.
- 03
How fast is it on the models our customers use?
Large, current open models, measured by us.
- 04
What does it cost, all in?
Hardware, power and operation per million tokens.
- 05
Where does it run, and who operates it?
On hardware we own, in the EU.
For fast inference, SambaNova's SN40L answers these questions best today, and every model we serve in Munich runs on it. Whatever runs underneath, you call the same API.
SN40L specifications
Chip: SambaNova SN40L RDU
- Process
- TSMC 5nm
- Package
- Two dies in one package (CoWoS)
- Compute units
- 1,040 (PCUs)
- Peak compute (BF16)
- 638 TFLOPS
- Memory per chip
- 520 MB SRAM, 64 GB HBM, up to 1.5 TB DDR
Rack: SambaRack SN40L-16
- Chips
- 16 RDUs
- Peak compute (BF16)
- 10.2 PFLOPS
- Memory
- 8 GB SRAM, 1 TB HBM, 12 TB DDR
- Power
- 7-14.5 kW in inference, 10 kW typical
- Cooling
- Air
- Size (H x W x D)
- 1994 x 610 x 1270 mm
- Weight
- 485 kg
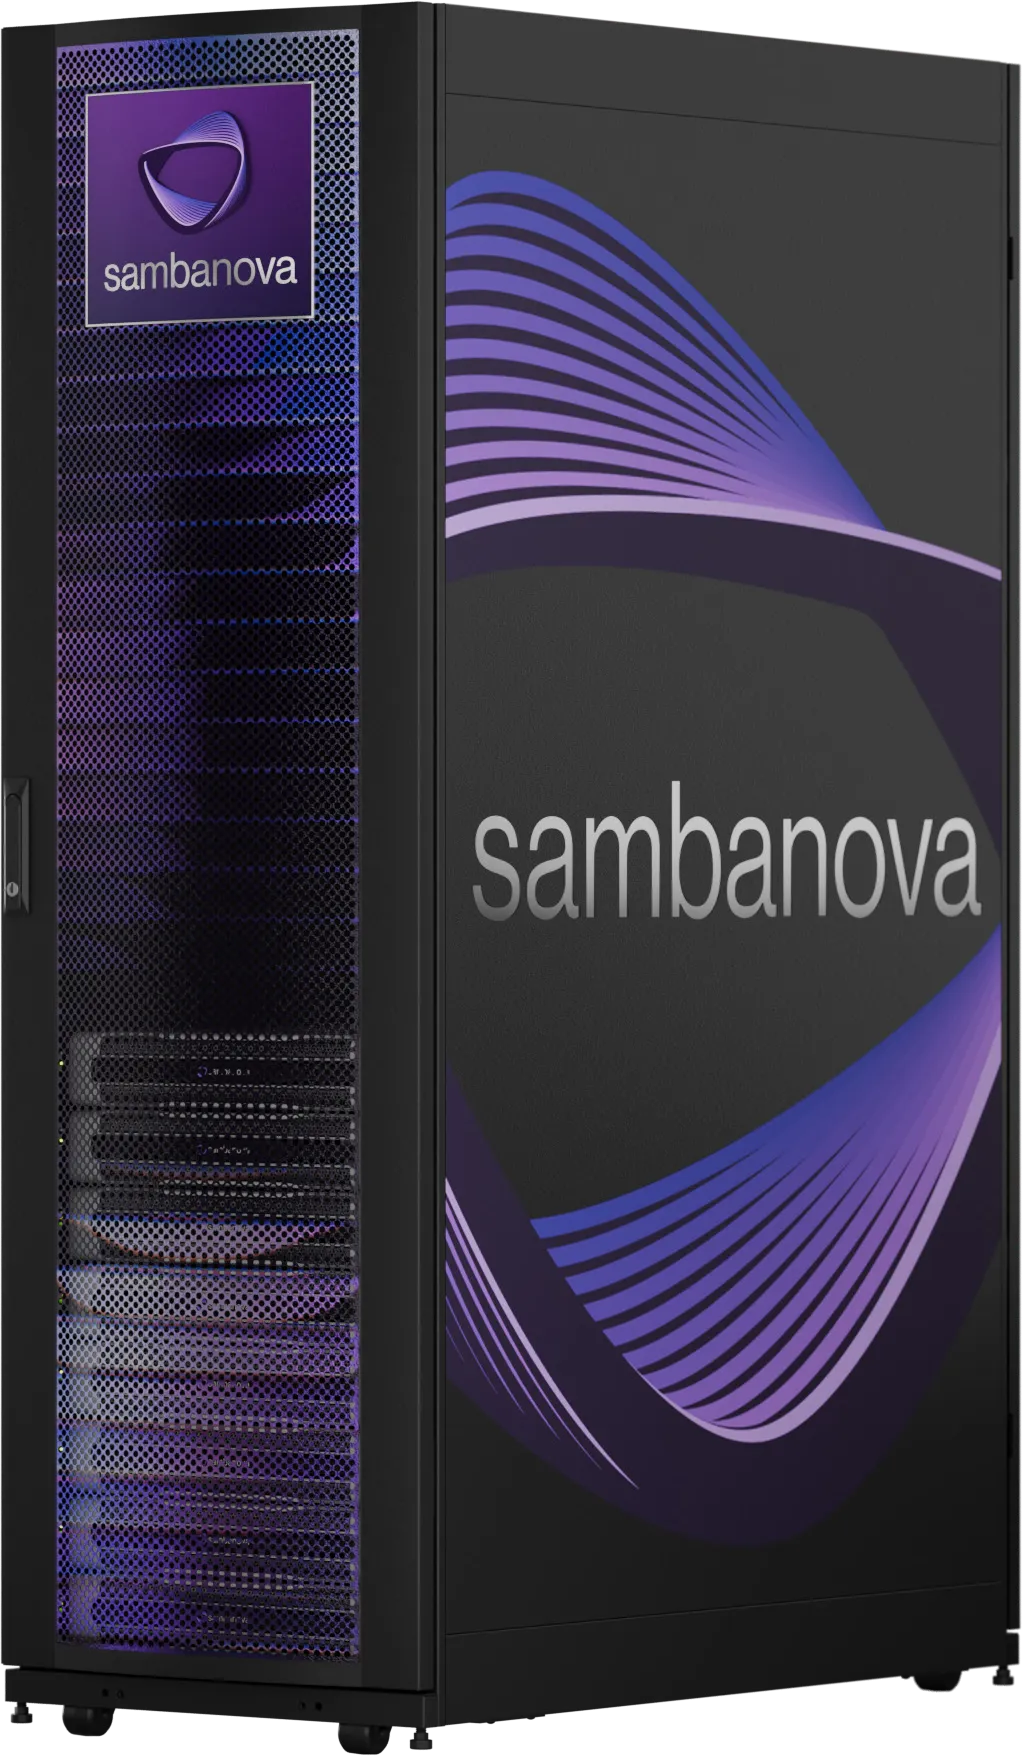
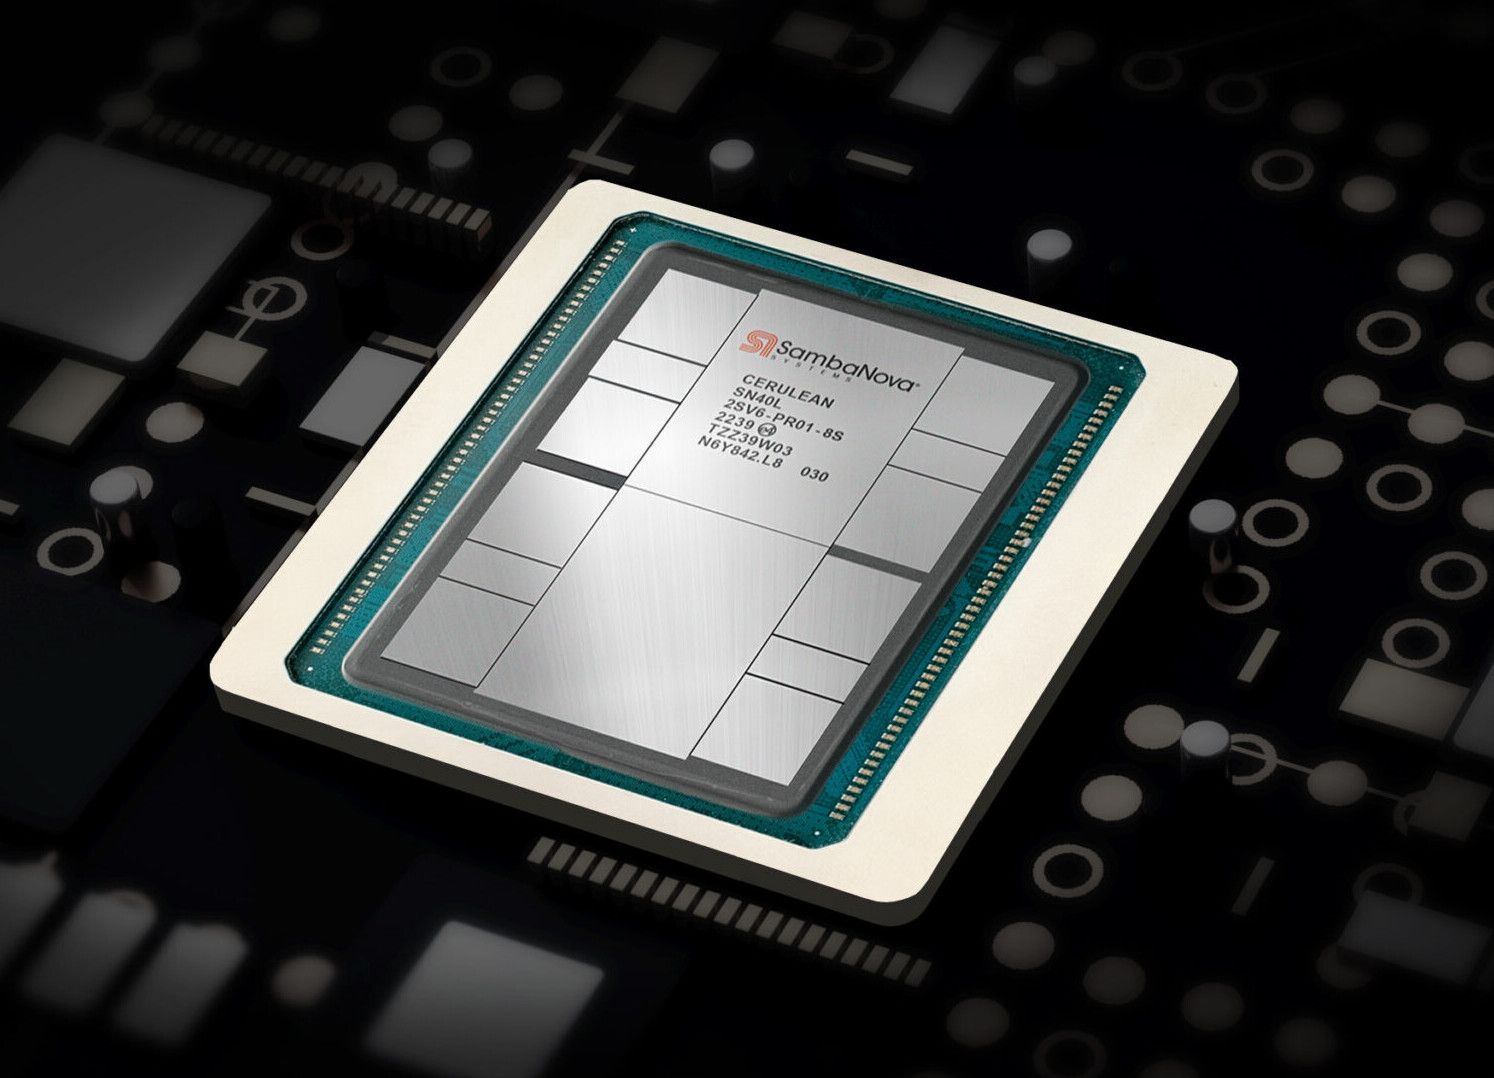
Our installation: 8 racks, 128 RDUs, at Equinix Munich 4.
In Munich, on hardware we own
- Equinix Munich 4, Germany. The racks belong to Infercom.
- The facility runs on 100% renewable electricity, through guarantees of origin.
- It cools with dry coolers and free cooling. The chips need no water for cooling.
- The facility holds ISO 27001, ISO 14001 and ISO 50001.
SambaNova's software serves the models, and SambaNova supports parts of the operation. What that means for your data
Questions
What is a Reconfigurable Dataflow Unit (RDU)?
SambaNova's AI chip. Instead of running a model step by step and going back to memory in between, it lays the model's operations out across the chip and streams data through them. Infercom runs the SN40L generation.
Why is dataflow faster than a GPU for inference?
While writing an answer, a GPU runs a model layer as many separate steps and writes the results in between back to memory. A dataflow chip runs the whole layer as one step and keeps those results on the chip, so it spends its memory bandwidth on the weights and answers sooner.
What hardware does Infercom run?
SambaRack SN40L-16 systems with SambaNova SN40L chips: 8 racks, 128 chips, at Equinix Munich 4. We chose them for fast inference.
Do you run SambaNova's SN50?
No. Our racks run the SN40L, and every figure on this page is for the SN40L.
How much power does a rack use, and does it need liquid cooling?
About 10 kW in typical use (7-14.5 kW in inference), and no: it is air-cooled and fits data centers built for regular servers.
Can one rack run several models?
Yes. Several models stay in memory at once and the rack switches between them in milliseconds. On a dedicated rack this lets you run your own fine-tuned checkpoints side by side.
Further reading
- SN40L architecture paper The chip, its three memory tiers and model switching, from SambaNova's engineers (arXiv).
- SambaRack SN40L-16 datasheet Rack specifications: chips, memory, power and dimensions (SambaNova).
- Intelligence per Watt Independent study of energy efficiency across AI accelerators, including the SN40L (Stanford, arXiv).
- Intelligence per Joule SambaNova on energy efficiency as a measure for AI infrastructure.
- 713 Tokens Per Second: The Architecture Behind Ultraspeed Our deep dive into dataflow and decode, with the measurements from May 2026.
- Glossary RDU, dataflow architecture, prefill vs decode, tokens per second.