AI inference for GCC teams
Enterprise-grade AI inference. Ready today.
Current open-weight models on purpose-built AI chips from SambaNova, up to 10x faster than GPU-based inference. Start self-service in minutes with an OpenAI-compatible API, or speak with our team about an enterprise contract.
Agents that don’t make you wait.
Answers before the pause gets awkward.
Your appointment is moved to Tuesday, 10:30. Anything else I can do for you?
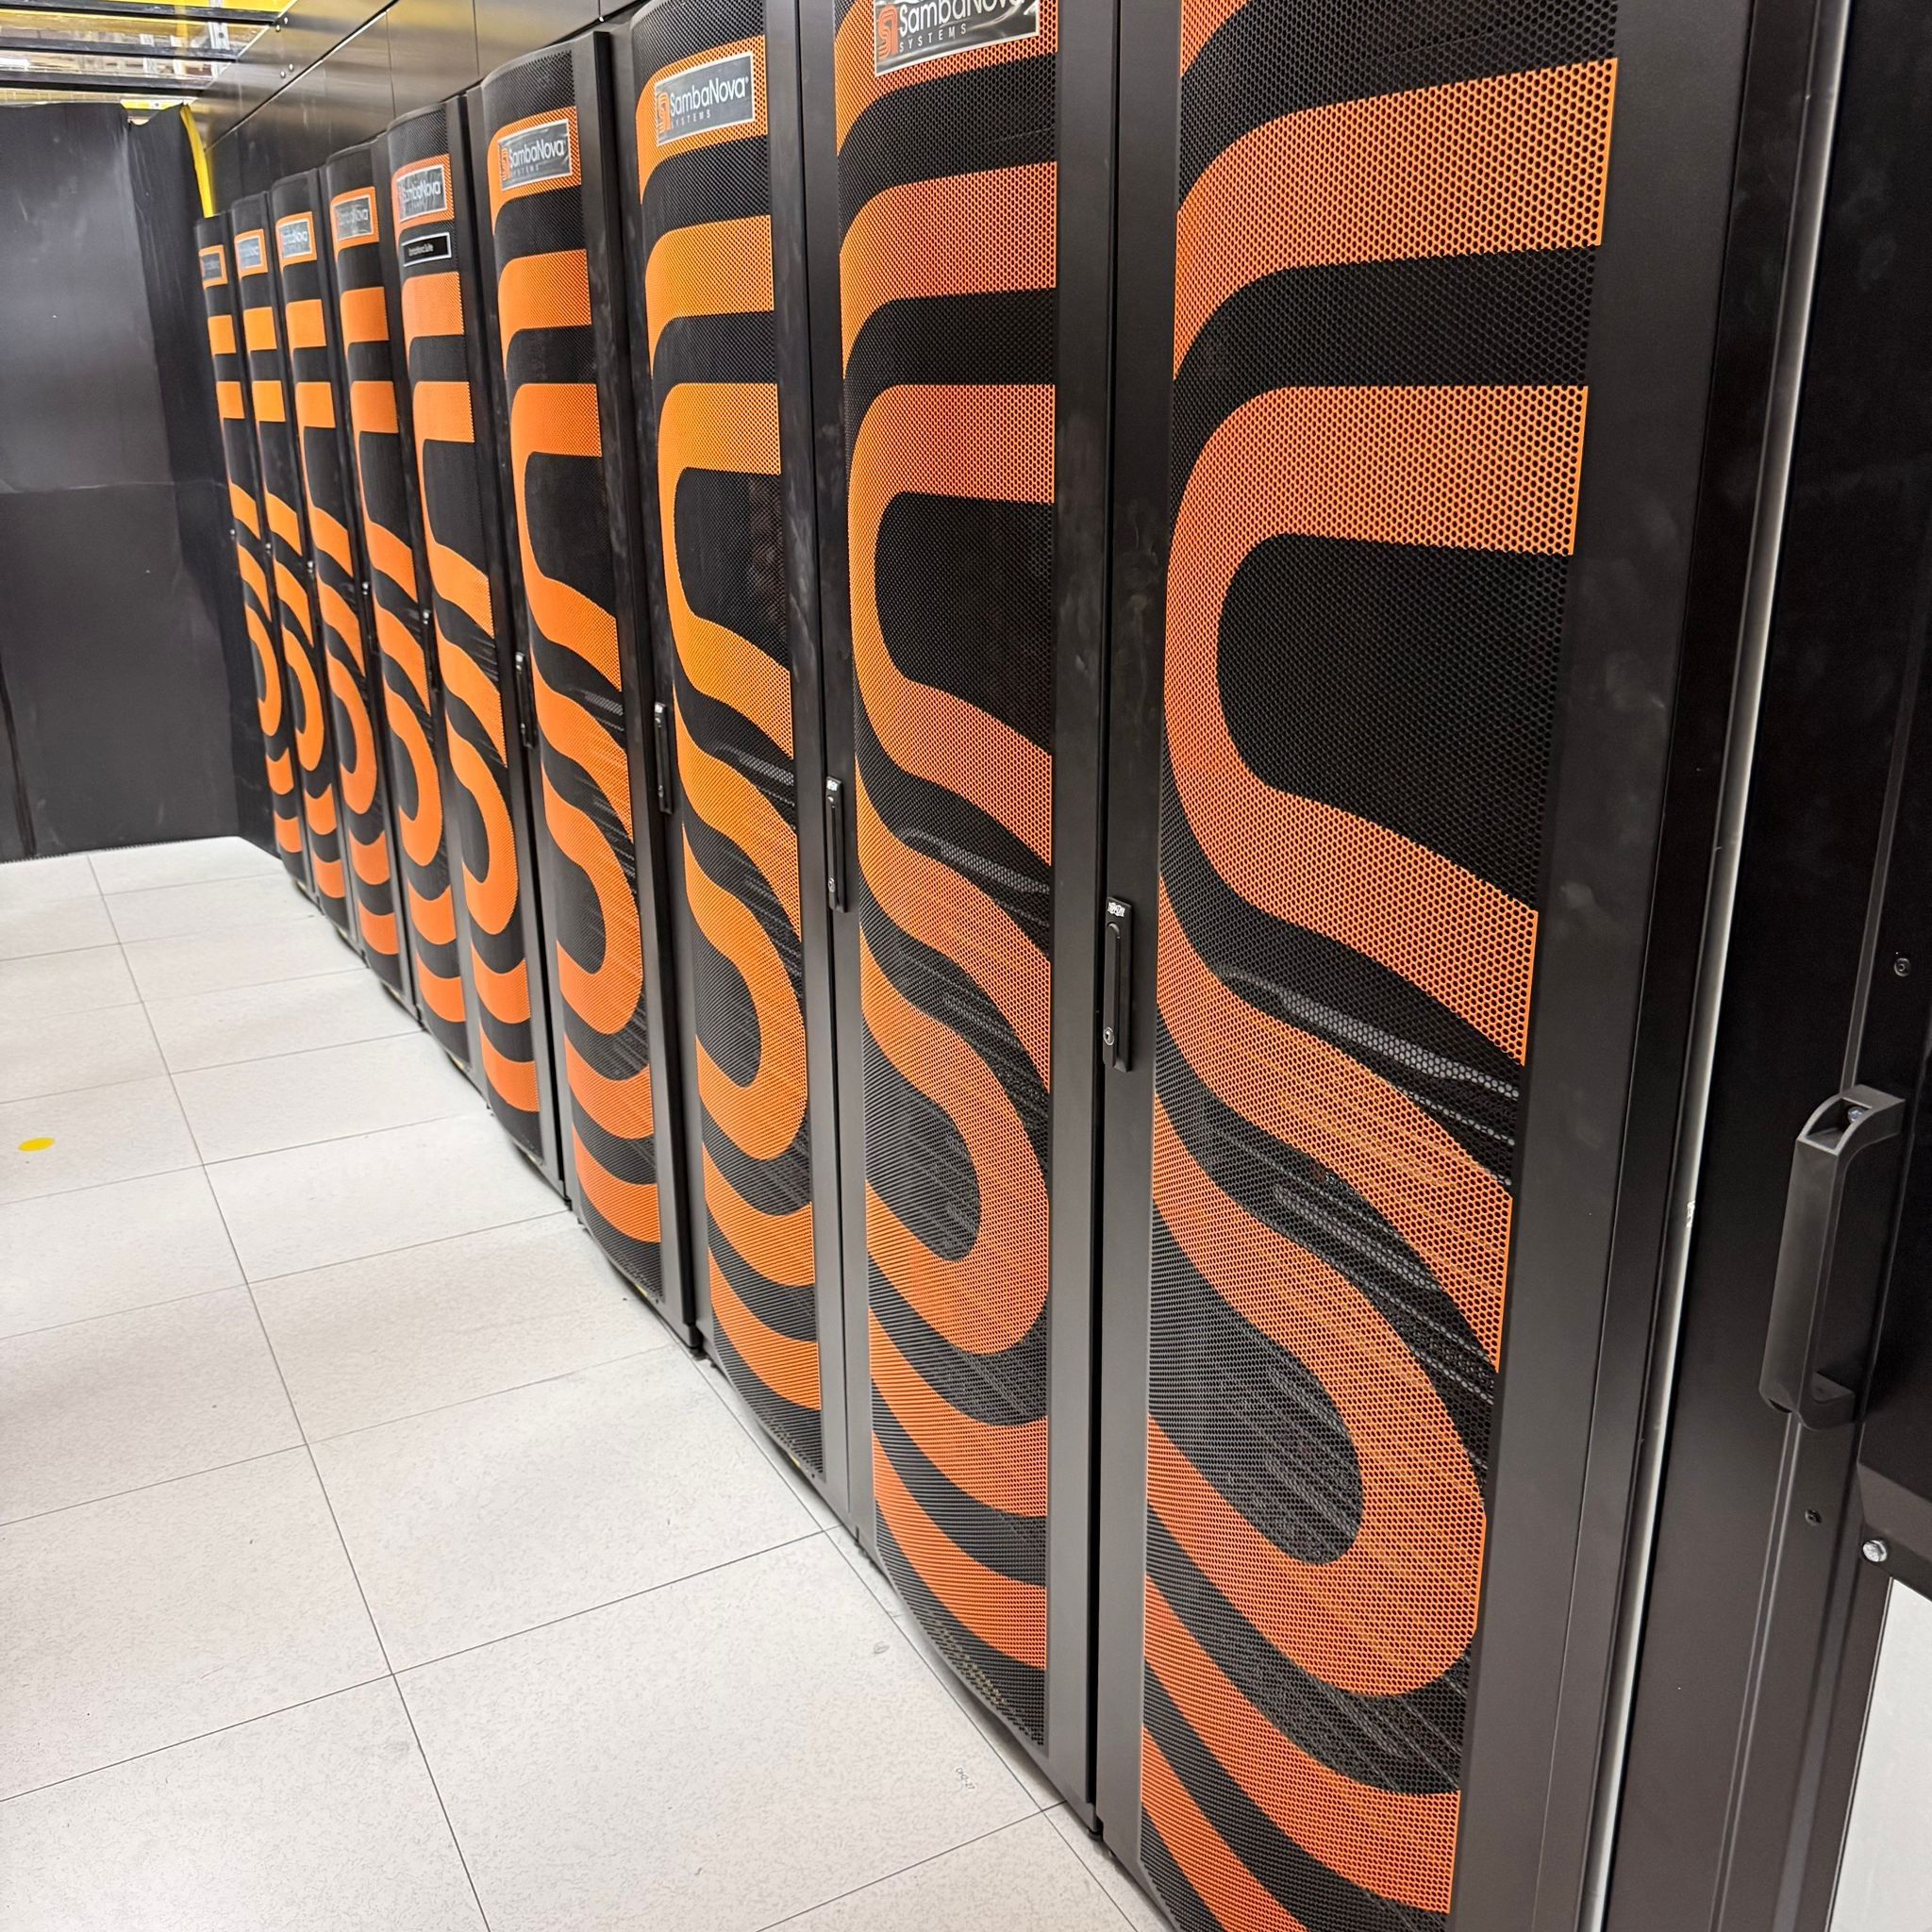
Powered by SambaNova.
- Purpose-built AI chips
- Up to 10x faster than GPUs
- ISO 27001 certified
People you can reach.
- Dedicated support
- Enterprise contracts
- From your first key to your own racks
Output Throughput, p50, 10K input / 1K output, single request. Last measured: July 2026.
Why Infercom
Built for production, not for demos
Measured speed
We publish what we measure on our production API, with the method. No promises we cannot show.
Powered by SambaNova
Purpose-built AI chips keep the model's working data next to the compute. That is what makes inference up to 10x faster than on GPUs.
Enterprise-grade
ISO 27001 certified, a DPA with Standard Contractual Clauses, dedicated support, and custom SLAs with Dedicated Capacity.
Open-weight, no lock-in
An OpenAI-compatible API and open-weight models. Switch models at any time, or run the same model elsewhere.
Models
Current open-weight models
Served at the precision their makers released them in. Speeds measured on our production API.
Use cases
Built for agentic workloads
Agentic coding
Faster answers mean faster iterations for coding agents and developer tools.
Agentic workflows
Multi-step automation, where every step waits for the one before.
Document processing
Up to 192K tokens of context for long contracts, reports and compliance documents.
Knowledge Q&A
Fast answers over your own documents and knowledge bases.
Try it
Switch in one line
Point your OpenAI SDK at our endpoint and pick a model. Nothing else in your code changes.
from openai import OpenAI

client = OpenAI(
    base_url="https://api.infercom.ai/v1",  # the one line that changes
    api_key="your-api-key",
)

response = client.chat.completions.create(
    model="gpt-oss-120b",
    messages=[{"role": "user", "content": "Hello"}],
)
Ways to run
Same API, from your first key to your own racks
Start self-service, then grow into guaranteed capacity or your own hardware. Your code and the performance stay the same.
Where your data runs
Clear about location
The Inference API runs in our data center in Munich, Germany (Equinix). ISO 27001 certified, with a Zero Data Retention Policy for prompts and outputs and a DPA with Standard Contractual Clauses.
Data that must stay in the UAE or the Kingdom?
Some sector rules require in-country hosting. On-Premises puts the racks in your own data center, with the same API and the same speed.
Who builds on it
Teams that build on Infercom





Ready to build?
Start with a pilot. Scale to production. Dedicated support when you need it.